Week 21. Production LLMs: RAG, agents, evaluation
Learn in the app: tutor, coding problems →
Core: BM25, dense retrieval and RRF, separate evaluation of RAG, the agent loop and prompt injection, a first ML system design · Depth: kinds of agent memory, your own agent harness, overfitting to your own eval, game theory (05-ГЛУБИНА) · ≈ 13 h core / 25 h total
This is the week the course becomes a product: the AI tutor in tutor-api/ is built
from exactly what is covered here. The main idea: **the quality of an LLM application
is determined less by the model than by what goes into the context, and by
how that is measured.**
Part 1. Retrieval
In plain terms. Three documents. D1: "RMSNorm divides a vector by its root mean square". D2: "LayerNorm subtracts the mean and divides by the standard deviation". D3: "The KV cache stores keys and values of past tokens". The question: "How does RMSNorm differ from LayerNorm?" Keyword search finds D1 (it contains "RMSNorm") and D2 (it contains "LayerNorm"), but not D3. D1 and D2 are inserted into the prompt before the question, and the model answers from them rather than from memory. If the search had returned D3, the model would have answered from memory or made something up. From a single answer you could not tell whether retrieval or generation was at fault. Hence the separate evaluation in part 2.
In plain terms. The term-frequency part of BM25 with k₁ = 1.2 (ignoring length): a word that appears 1 time scores 1.0,
2 times: 1.375, 10 times: 1.96. The ceiling is k₁ + 1 = 2.2, however many times you repeat it.
So spam that repeats "RMSNorm" a hundred times scores less than 2.2 on that word.
And a document where "RMSNorm" appears twice and "LayerNorm" once scores 1.375 + 1.0 = 2.375, given equal IDFs.
- Retrieval, that is, finding the fragments that get placed into the model's context
- BM25:
Σ_{t∈q} IDF(t) · f(t,d)(k₁+1) / (f(t,d) + k₁(1 − b + b·|d|/avgdl)). Take each term apart: IDF (the log of the inverse fraction of documents that contain the word): a rare word is more informative;k₁controls saturation (ten repeats of a word are not ten times better than one);bcontrols length normalization (in a long document a word also shows up by chance) - Dense retrieval: a bi-encoder (the question and the document are encoded into vectors separately): documents are encoded ahead of time, so search is cheap; a cross-encoder (the question and the document go into the model together): more accurate, but it needs a pass for every pair. Hence the cascade: cheap recall → expensive rerank
- BM25 wins on exact terms, names and rare words ("SwiGLU"); dense retrieval wins on paraphrases. Takeaway: they fail on different queries, hence the hybrid
In plain terms. BM25 ranks D1 first and D2 second; dense retrieval ranks D2 first and D1 third. With k = 60,
D1 gets 1/61 + 1/63 ≈ 0.03227, and D2 gets 1/62 + 1/61 ≈ 0.03252.
D2 wins: it is high in both lists, while D1 is high in only one. And you never had to add BM25 scores to cosines.
- RRF (Reciprocal Rank Fusion, merging lists by rank):
score(d) = Σ_r 1/(k + rank_r(d)),k ≈ 60. Why ranks and not scores: the scales of BM25 and cosine are not comparable, normalizing them is fragile, and ranks are always comparable - Chunking (cutting documents into pieces that become the units of search) is always a trade-off: a small chunk is found more precisely but loses context. Cutting along the document's structure (headings) is usually better than a fixed window
Depth: local multimodal embeddings. EmbeddingGemma 2 illustrates a shared space for text, code, images, video and audio. Its card lists 740M parameters in total and 270M for text-only mode; it does not generate answers. In plain terms. One million 768-dimensional float32 vectors need 3.072 GB; 128 dimensions need 0.512 GB, excluding index and metadata. Matryoshka training enables useful vector prefixes, but truncation requires re-normalization; arbitrary embeddings need not support this operation. Mini-experiment: freeze questions and labels; compare BM25, dense retrieval and RRF on identical documents. Measure recall@k, latency and memory by language and modality. Tune on development data and report on held-out data. Follow the model card's query/document formatting. A local encoder alone does not guarantee private RAG: inspect the generator, logs and telemetry too.
Part 2. Evaluating RAG
- Evaluate retrieval and generation separately: recall@k (the fraction of all relevant fragments for a question found in the top
k) and MRR (the mean of1/rankof the first relevant fragment) tell you whether the needed fragment was found; faithfulness (the answer relies on what was retrieved rather than being made up) and correctness tell you how the model used it. Without this separation you cannot tell where the error is - A golden set: 50–100 questions with the correct fragments marked. Every change to the prompt or the index means running the set before and after and comparing with the statistics of week 18: McNemar for binary hit@k on the same questions, paired bootstrap for differences in recall@k. Hit@k means finding at least one relevant fragment; it equals recall@k only with one gold relevant fragment
Part 3. Agents
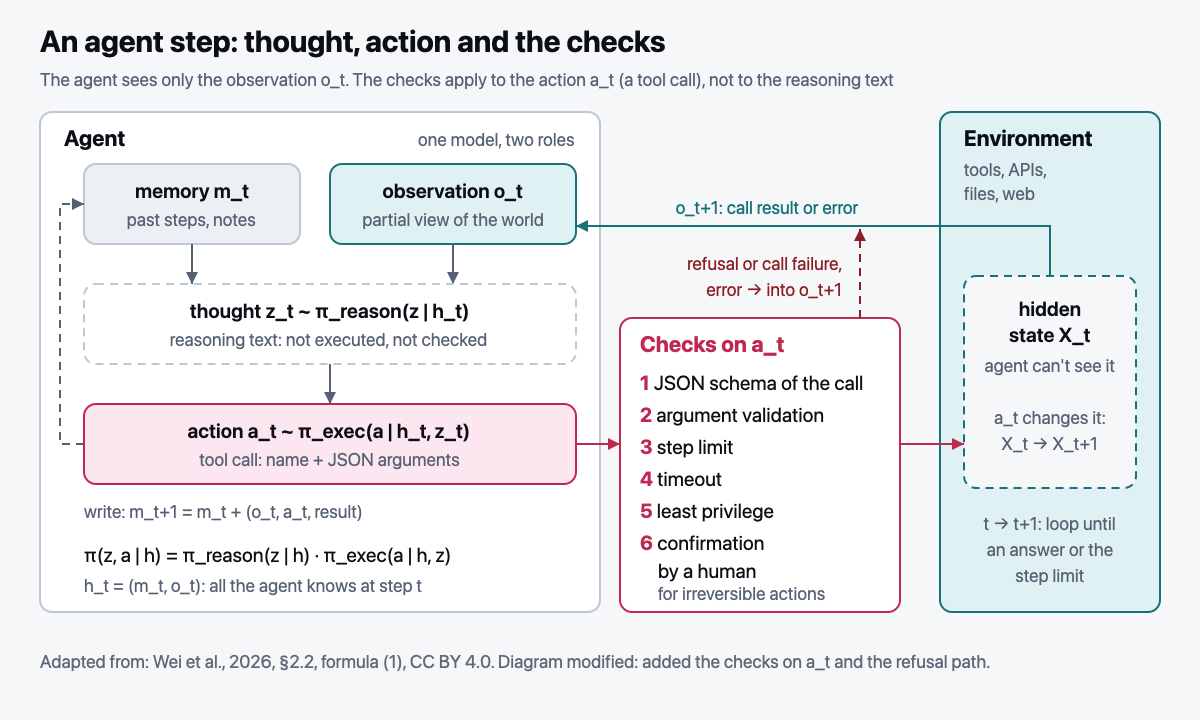
In plain terms. The agent's task: "delete the project's temporary files". The reasoning is flawless:
"temporary files live in ./tmp, I will delete only those". But the tool call is:
delete(path="/home/user", recursive=true). Checking the reasoning text would have found nothing.
Checking the arguments ("the path must be inside ./tmp") catches the error before execution,
and the refusal is returned to the agent as an observation.
Four refinements based on a recent survey of agentic reasoning (Wei et al., 2026, 29 authors, accepted to TMLR; licensed CC BY 4.0, so the diagrams can be redrawn with attribution):
- Thought and action are not the same thing. What you need to check and log are the *arguments of the tool call*, not the reasoning text: the reasoning can be convincing while the call is wrong.
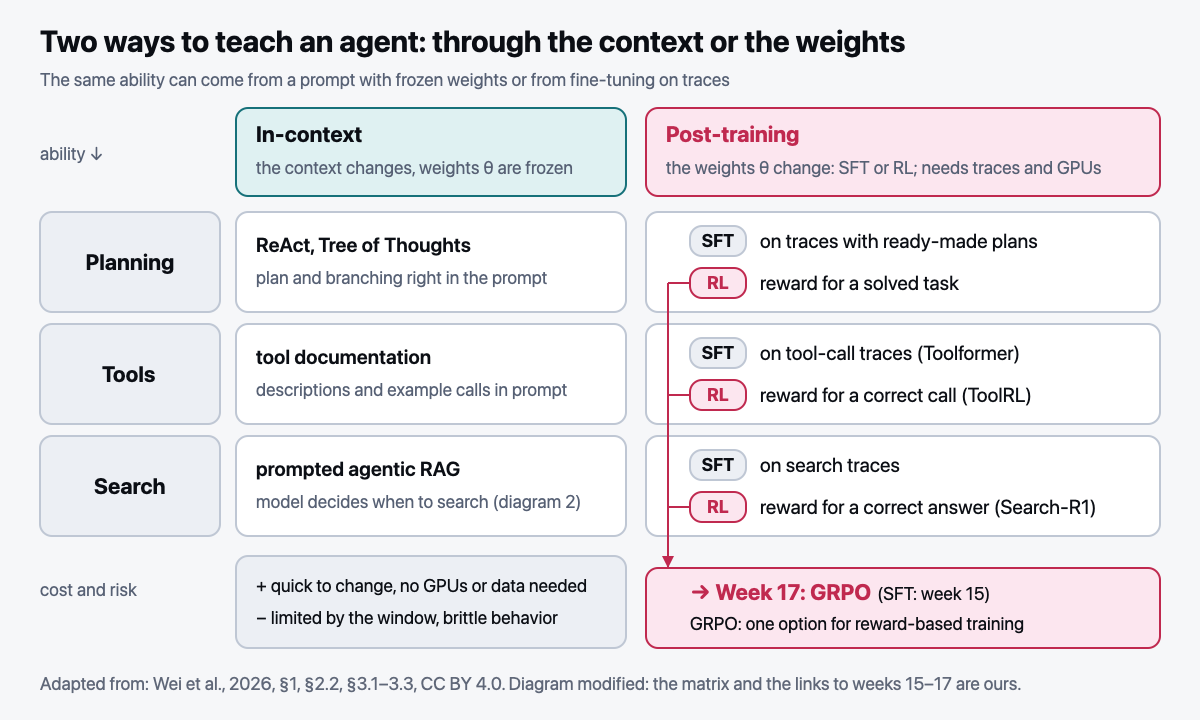
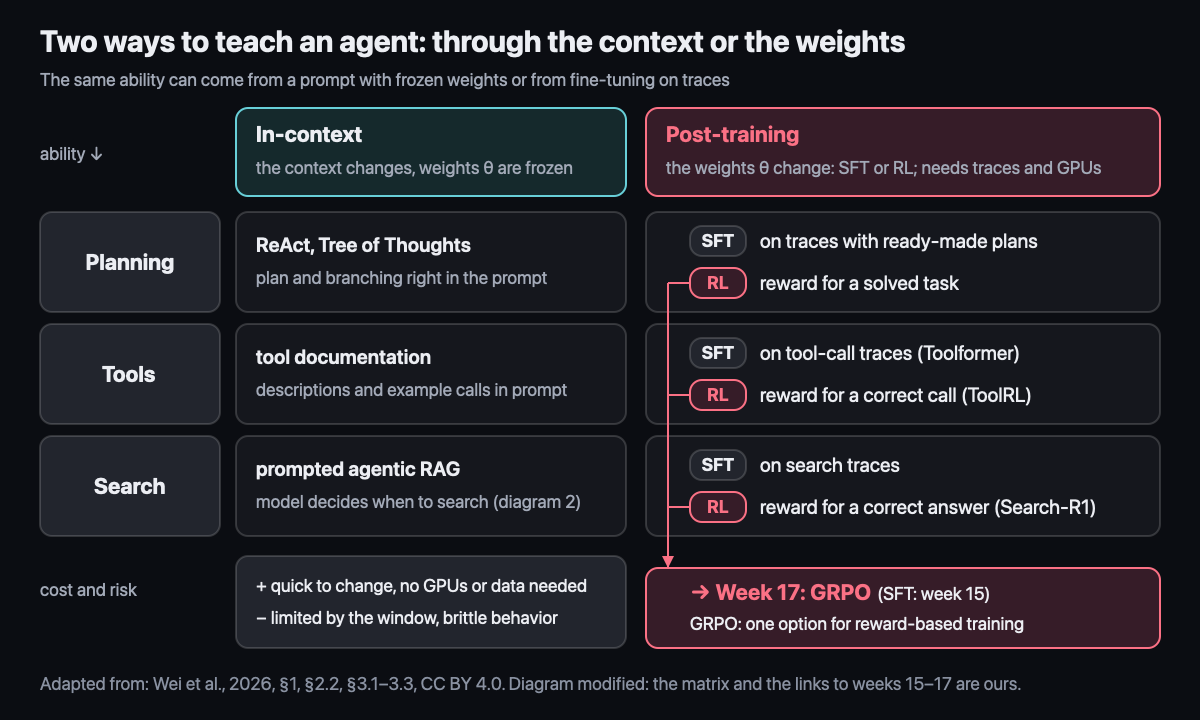
- Tool-use skill does not come only from the prompt. It can be trained (SFT on call traces, or RL with a reward for task success). This is a direct bridge to week 17 (Toolformer, 2023, the first paper in this line).
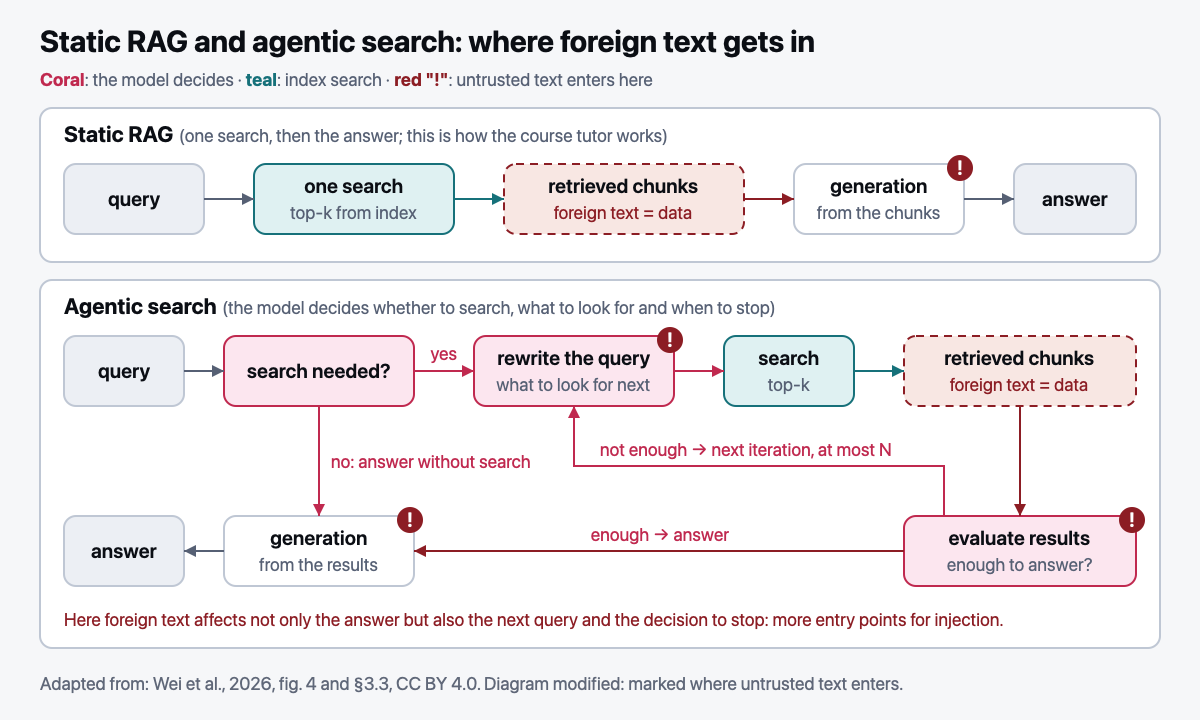
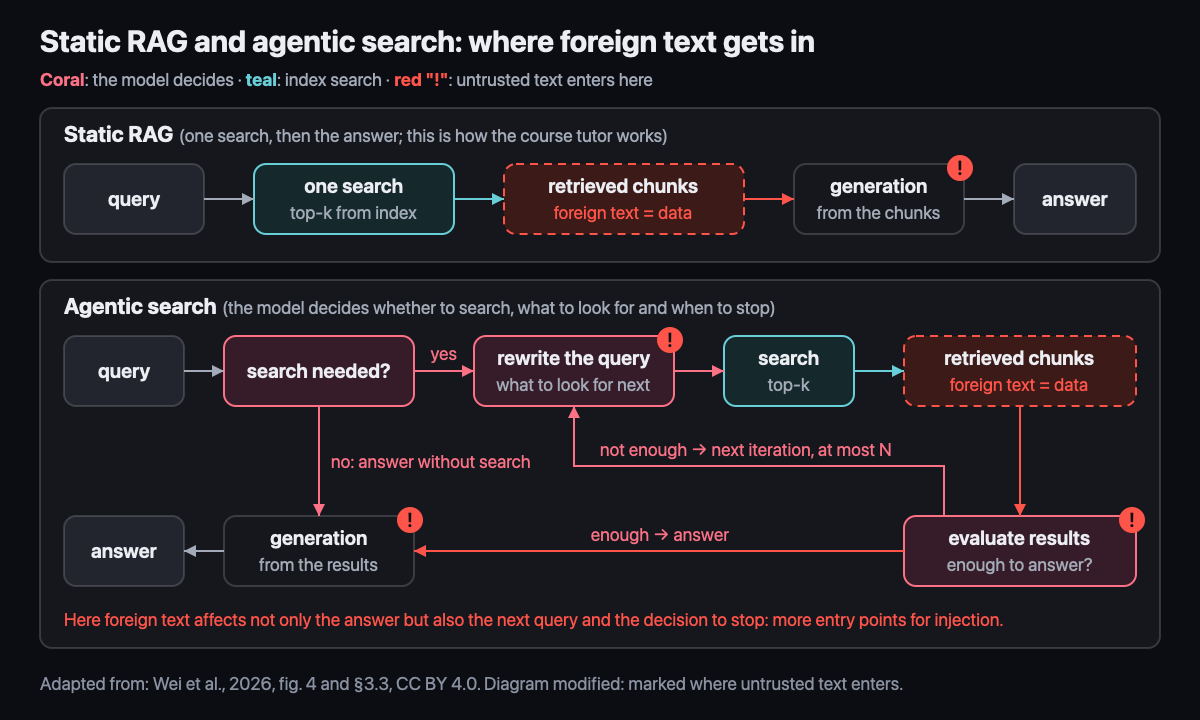
- Search can be static or agentic. Static RAG: one query → fragments → answer. Agentic: the model itself decides what to search for, reformulates, and stops. The course tutor is static; moving to agentic search is left as the week's exercise. Agentic search can also be taught with RL and a reward for a correct final answer (Search-R1, 2025).
- Memory is part of the agent's state, not "just more context": what to keep between steps, what to keep between sessions, and how that affects reproducibility.
Three kinds of agent memory
In plain terms. An assistant agent manages a student's schedule. The request: "move tomorrow's office hour to Friday".
Working memory at this step: the request itself, the response of calendar.list(date="tomorrow") (one meeting at 15:00)
and the previous step, about 2k tokens in total; nothing of it survives the session.
External memory: 500 notes about the user in a database, of which 3 reach the context, found by searching for
"office hour", and one of them says "no meetings on Fridays after 16:00".
Procedural memory: a "reschedule a meeting" skill written down as an instruction (check conflicts → offer two slots →
wait for confirmation → call calendar.move); it is not about this user but about how to do the job.
A failure in each memory looks different: the agent forgot a condition from early in a long dialogue (working memory was compressed),
booked Friday at 17:00 (search missed the note), moved the meeting without confirmation (the skill was not loaded).
- Working memory (everything in the context at the current step): precise and fast, but bounded by the window and paid for in tokens at every step. When it overflows it is compressed, as in the lab below
- External memory (a store outside the model from which the needed items are fetched by search or a database query): essentially RAG over the agent's own history, so recall@k and the separate evaluation from part 2 apply to it. The new risk is in writing: whatever the agent stored, it will later read as fact. Tool output that lands in memory is still data, not instructions (part 4)
- Procedural memory (learned skills: instructions, templates, tested functions the agent applies to new tasks): kept in the prompt (in-context) or moved into the weights by training on successful trajectories (post-training, diagram 3). Reflexion (Shinn et al., 2023) is a middle ground: after a failed attempt the agent writes a verbal note about its mistake and reads it on the next attempt, with no weight updates
- External and procedural memory change between runs. So the run log records their version (a database snapshot, a hash of the skill set); otherwise two runs of the same agent cannot be compared fairly
- Shared procedural memory across many agents. An example: the open project universal-modder (skills for agents
that build game mods) keeps field notes. When an agent finishes, it writes down the exact versions that worked,
the route it took and why, how the result was verified, and the gotchas as "symptom → cause → fix". The next
agent searches the notes first and avoids the same traps. To keep the base from piling up confident mistakes,
it has three safeguards: a program checks the format (required fields, an honest "verified or not" status), a
note enters the shared base through a pull request only after a human agrees, and game files or other people's
code never go into notes. The risk is the same as with external memory: the agent will read someone else's
conclusion as fact, so the "how it was verified" field matters more than "what was done", and a note written for
another version gets re-checked. In this course the known-pitfalls section of
AGENTS.md(«Известные подводные камни») works this way
The survey covers neither MCP nor prompt injection, so for security we still rely on OWASP.
- Tool use: the model emits a call that follows a JSON schema, the code executes it and returns the result into the context. The "reasoning → action → observation" loop (ReAct). MCP (Model Context Protocol) is an open protocol for connecting tools
- Engineering matters more than the prompt: step limits, timeouts, idempotency (calling again does not change the result), argument validation, least privilege. If the steps are known in advance, you need a pipeline, not an agent
- Several agents with different rewards are playing a game. Two agents share an API quota: if both hold back, each gets 4; if one grabs, it is 6 versus 1; if both grab, 2 each. Grabbing pays off whatever the other agent does, so both end up at (2, 2), even though (4, 4) is better. This is a Nash equilibrium (no one gains by deviating alone): without shared rules, agents slide into it. A debate between two models in front of a judge (Irving et al., 2018) is designed as a zero-sum game where telling the truth pays off in equilibrium; this is a hypothesis, tested by experiment
Lab. Your own harness (the scaffolding around an agent)
In plain terms. An agent solves a task in 80% of runs. The pass@3 metric (at least one success in three attempts)
equals 1 − 0.2³ = 0.992, and the agent looks nearly perfect. But a user runs the agent once and expects
it to work every time. Reliability pass^3 (success in all three attempts) equals 0.8³ = 0.512.
Same model, and the number is 99% or 51% depending on what you count.
- A 50–80 line loop without a framework: the model emits a tool call or a final answer, the code executes the call and returns the result as an observation; a step limit and a context token limit
- A tool error (an exception, a timeout, an unknown name, bad arguments) doesn't crash the loop but is returned to the model as an observation with the error text: this way the model can recover
- Context compression: when the history no longer fits the budget, old observations are replaced with a short summary, while the task statement and the last step stay verbatim
- In tests, the model is replaced with a recorded sequence of actions: the loop is checked deterministically and without an API. The trainer has an "Agent loop with tools" problem in exactly this form: a convenient way to start the lab
- Evaluation: 20–50 tasks with a checkable outcome (a test passes, a file is in the right state), 5 runs per task; success rate, pass^k, average number of steps and tokens. Trajectories of successful runs become data for SFT (week 15), and the checkable outcome becomes the reward for GRPO (week 17)
Context edits and the prefix cache. In plain terms. The agent's context holds 10,000 tokens, and their keys and values are already in the prefix cache (week 11). The agent replaces an old observation at positions 2,000–4,999 (3,000 tokens) with a 300-token summary. The prefix cache matches only up to the first changed token, so a standard server re-runs the summary plus all 5,000 tokens after the edit: 5,300 tokens of prefill. Had the agent compressed the last observation at the end of the context, only 300 tokens would need recomputing, almost 18 times fewer. Hence a harness rule: edit the context as close to the end as possible, and keep the beginning (system prompt, task statement) unchanged.
- You can go further and hand context management to the model itself: the context is stored as a file the model edits with the same commands it uses for ordinary files (append, replace a span, delete), and with no edits new tokens are simply appended. This is how Context Language Models (Shao et al., 2026) work: such a model beats a harness with a fixed compression rule on accuracy while spending fewer FLOPs, and when it is trained with GRPO (week 17) the advantage gets a bonus for lower recomputation cost, but only among successful trajectories, so the model doesn't learn to save compute at the expense of the answer
- The cache after an edit doesn't have to be thrown away entirely. The surviving 5,000 tokens just moved 2,700 positions
to the left. In RoPE the key at position
pis rotated by an angle proportional top, so the shift reduces to rotating the stored key by−2,700positions; values don't change, and only the 300 new tokens need computing. This is an approximation: the states of the surviving tokens were computed while the removed text was still visible, so the trick is checked on answer quality, not only on speed
Overfitting to your own evaluation. In plain terms. A set of 30 tasks, ten prompt edits in a row, each kept if the success rate went up. On those 30 tasks the rate climbed from 60% to 80%, while on 20 held-out tasks it stayed at 60%: the edits learned quirks of specific tasks instead of making the agent better. It gets worse when the agent itself edits its harness in a loop of "change → run the eval → keep if it went up": the number can rise with nothing improved, for example by memorizing the answer to a familiar task or by giving the agent a tool through which the reference answer is visible. This is Goodhart's law (a metric that becomes a target stops measuring) in miniature. The defense is simple: tune on one part of the set, report on a frozen other part, and check that both go up; keep reference answers where no tool of the agent can reach them; read trajectories, not just the final number. How such a loop works in practice: Lance Martin, automating eval design and hill-climbing (claude.dev, 2026).
Agent evaluation: symbol search versus behavior understanding. CABRA
separates function search, call-graph traversal, runtime resolution and instruction-following complexity.
Tools help, but understanding-intensive tasks still expose failures.
In plain terms. Finding price() among 100 files is easy with search. Distinguishing two namesakes,
one returning a price before tax and another after tax, requires checking behavior.
Mini-experiment: vary graph depth, distractor functions and constraints independently. Compare an
unaided model with an agent using the same model version and fixed budgets. Check hidden behavioral
tests and unintended changes; report success, tokens, time and failure causes. Execute generated
code only in an isolated environment without secrets.
Accepting an LLM service through scenarios. Directory names do not prove reliability.
Write a table of scenario, expected behavior and test: another tenant's document is inaccessible;
a model timeout ends the request and releases its quota reservation; a duplicate webhook does not
grant access twice; client disconnection cancels generation; a prompt change passes a separate eval;
logs contain no keys. Start with existing auth, accounts, billing, tutor modules and
tutor-api/ tests, without reorganizing the repository just to match a folder diagram.
Integration tests and model evaluations answer different questions.
Part 4. Cost, security, serving
- Prompt caching: put the stable parts (system prompt, documents) at the start and the changing parts at the end, otherwise the cache does not hit
- Prompt injection: text from retrieval and from tools is data, not instructions. Indirect injection through a document remains the main risk of RAG
- Serving: vLLM and SGLang with their PagedAttention, continuous batching, prefix caching (week 11)
Part 5. A first ML system design problem
Everything above comes together in an interview round where you are asked to design a whole system (format and rubric: РУБРИКИ.md, section 7). Talk through the prompt "an assistant over 10,000 internal documents with access rights" out loud in 45 minutes, step by step: requirements → back-of-the-envelope estimate → architecture → data → quality evaluation → serving → failure modes. Something to lean on: the course tutor is built the same way, and almost every one of its decisions (hybrid search, a gold set, injection defenses) is covered this week. The trainer has problems on BM25 and RRF: this is the retrieval core that system design draws as a single box, and it helps to remember what's inside. The other prompts are in section 8 of the question bank.
Code → nanolm/retrieval.py: BM25 from scratch (tokenization, IDF, k₁, b);
CharNgramEncoder, vector search over character n-grams instead of a neural
encoder (no semantics, but robust to word forms, and it fails in different places than BM25);
reciprocal_rank_fusion, HybridRetriever, recall_at_k. python -m nanolm.retrieval prints
recall@k for the three methods on a built-in set. The exercise is in exercises_en/retrieval.py;
check it with NANOLM_IMPL=exercises_en pytest tests/test_retrieval.py -v.
A live example is in tutor-api/src/retrieval.ts: read how the tutor's search
works and compare it with your implementation. Practice: 30 questions over PROGRAM/*.md
with the correct section labeled, and recall@5 for BM25, dense and hybrid in one table.
Math (Track D): D33: the secretary problem; D34: Monty Hall with n doors.
Interview question of the week: "A RAG system gives wrong answers. How do you find the cause?" Structure: (1) separate the cases: was the needed fragment in the context? (2) if not: recall@k on the golden set, chunking, hybrid search, query rewriting; (3) if it was: its position in the context, conflict with parametric knowledge, the prompt; (4) lock the case in as a regression test; (5) show metrics before and after.
Sources: Robertson & Zaragoza, The Probabilistic Relevance Framework: BM25 and Beyond (2009); Cormack et al., Reciprocal Rank Fusion (2009); Lewis et al., Retrieval-Augmented Generation (2020); Yao et al., ReAct (2022); Schick et al., Toolformer: Language Models Can Teach Themselves to Use Tools (2023); Shinn et al., Reflexion: Language Agents with Verbal Reinforcement Learning (2023); Jin et al., Search-R1: Training LLMs to Reason and Leverage Search Engines with Reinforcement Learning (2025); Wei et al., A Survey of Agentic Reasoning for Large Language Models (2026), §2.2, §3.2–3.3, §4.2 as a map of the field; Shao et al., Context Language Models (2026), where the model edits its own context.
Deeper: 05-ГЛУБИНА, section "Weeks 17 and 21. A little game theory".
Week outcomes
- I can implement BM25 from scratch and explain the roles of IDF,
k₁andbon a concrete example. - I can build hybrid search with RRF and explain why you merge ranks and not scores.
- I can build a golden set and compute recall@k for three retrievers.
- I can diagnose a RAG system's error in 5 minutes, separating a retrieval failure from a generation failure.
- I can write an agent loop that handles tool errors and explain the difference between pass@k and pass^k.
- I can compute how many tokens must be recomputed after an agent edits its context, and explain why edits are kept near the end.
- I can tell working, external and procedural agent memory apart and, from a failure symptom, say which one to look in.
- I can design a RAG system in 45 minutes step by step from requirements to failure modes, backed by numbers.
Self-check
- Why does BM25 need frequency saturation and document length normalization?
- When does BM25 beat dense retrieval, and when is it the other way around? Give an example for each case.
- What is indirect prompt injection, and how do you protect the tutor from it?
- The agent forgot a constraint the user stated a month ago. Which of the three kinds of memory do you look in, and how do you check it with a number?
- After ten prompt edits the agent's success rate on your set rose from 60% to 80%, yet users noticed no difference. What went wrong, and how do you change the procedure?
- The agent's context is 8,000 tokens, and it replaces tokens 1,000–2,999 with a 200-token summary. How many tokens does a server with a standard prefix cache recompute, and how many when surviving states are reused? By how many positions, and how, do you shift their keys?
- The agent found a note in the shared base saying "on version 1.4 it works through loader X", but the user has version 1.6. Which fields of the note help decide whether to trust it, and what should the agent do before writing its own note?
Mock interviews of the week (5 and 6 of 12). (5) ML system design, session D: a prompt from section 8 of the question bank, but not the one worked through in part 5. (6) ML coding, session B: beam search from an empty file.