Week 15. SFT and data
Learn in the app: tutor, coding problems →
Core: SFT and loss masking, chat templates, LoRA and QLoRA, data deduplication and filtering · Depth: distillation and pruning, the data lab of week 15b · ≈ 11 h core / 21 h total
From this week on, we no longer pretrain the model but refine it: a pretrained LLM continues text rather than answering questions. SFT is the first stage of post-training, and the RL of weeks 16–17 starts from the SFT model. This week also covers two tools without which fine-tuning does not fit the budget and a benchmark proves nothing (week 18): LoRA, and clean data with decontamination.
- Instruction tuning (SFT, fine-tuning on "instruction → response" pairs), chat templates (the format that glues a dialogue into one string), special role tokens (they mark where the user's turn is and where the assistant's is)
In plain terms. Example: <user> What is 2 + 2? <assistant> 4 <end>. Say this is 8 prompt tokens and 2 response tokens.
Without a mask, 8 of the 10 terms in the mean loss belong to the prompt. This is a share of positions,
not a guaranteed share of the gradient norm. The objective includes predicting user text. Prompt masking is commonly used when the objective is to learn responses. With a mask, the prompt labels are replaced by ignore_index (−100),
and the loss is computed only where 4 and <end> are predicted.
With long prompts the skew is worse: a 900-token document and a 100-token response: without a mask the response would contribute 10% of the mean-loss terms, not necessarily 10% of the gradient.
- Prompt-loss masking: which positions enter the training objective and whether that matches the task
In plain terms. Asked "capital of Australia?", the teacher outputs a distribution: Canberra 0.7, Sydney 0.2, Melbourne 0.1.
A one-hot label says only "Canberra". A soft label adds more: Sydney is a plausible mistake, Melbourne a less plausible one.
A student trained on (0.7, 0.2, 0.1) gets more information from a single example.
The loss here is cross-entropy with the teacher's distribution, and the student's log softmax is computed via logsumexp (week 4).
- Synthetic data, distillation (the student learns from the teacher's outputs, including from logits;
this is exactly where the instability of
logsumexpshows up) - Data curation: deduplication (MinHash/LSH), quality filters, decontamination (removing training texts that overlap with test sets)
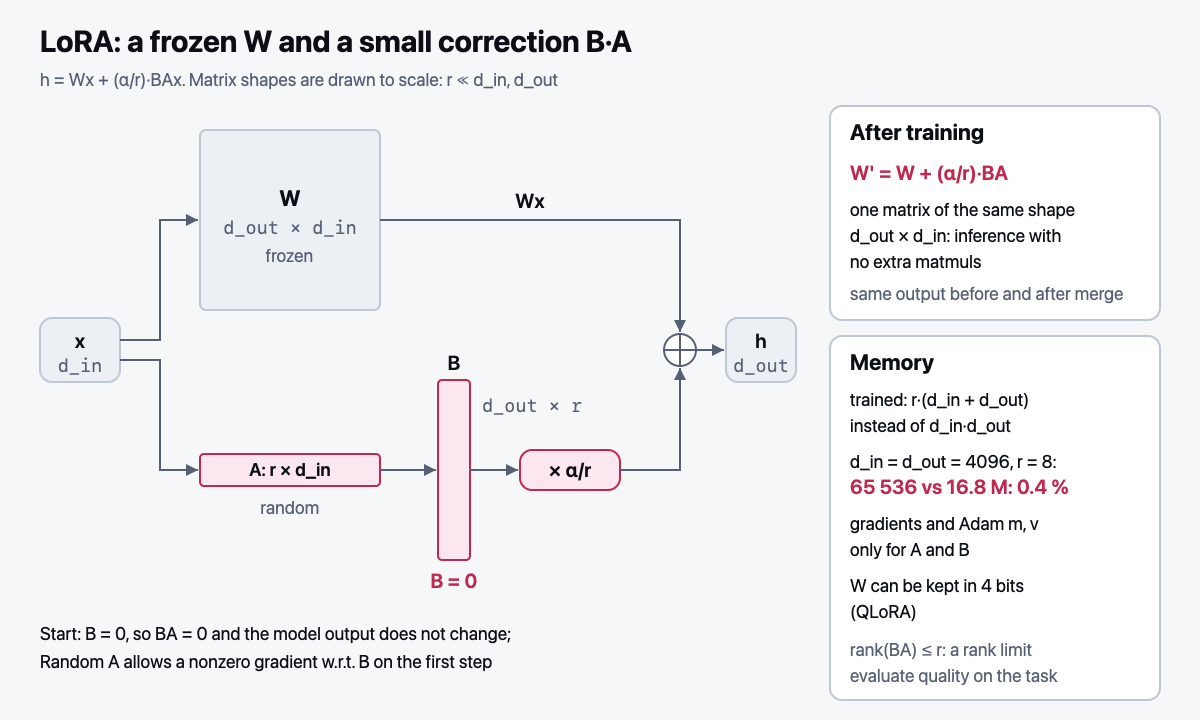
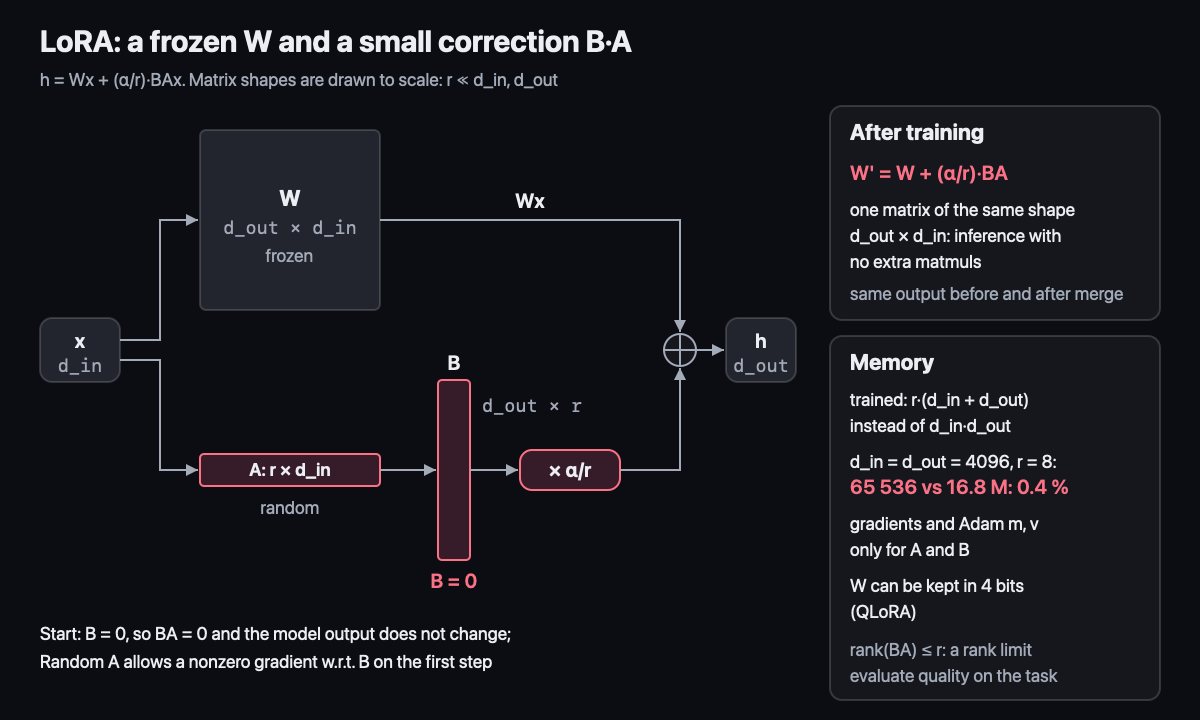
In plain terms. A layer matrix W of size 4096×4096 holds 16.8 million numbers, and it is left untouched.
On top of it goes a correction ΔW = B·A: B of size 4096×8, A of size 8×4096, 65,536 numbers together, 0.4% of W.
The correction is constrained in shape. Rank 1 is b·aᵀ: with b = (1, 2) and a = (3, 0, 1) you get
[[3, 0, 1], [6, 0, 2]], and the second row must be a multiple of the first.
Rank 8 means at most 8 independent directions of change for the whole layer.
That is enough if the needed change is nearly low-rank, and not enough if it is not.
Adapter scaling. Standard LoRA uses ΔW = (α/r)BA. This controls the contribution; it does not guarantee rank-independent training. Recheck quality and stability when changing r. The rsLoRA variant uses α/√r; compare recipes at equal budgets on held-out data.
- LoRA / QLoRA: low-rank decomposition (a weight correction as the product of two narrow matrices), where to insert adapters, what memory it saves. QLoRA is the same on top of a frozen model compressed to 4 bits (quantization, details in week 14)
Code → nanolm/lora.py: LoRALinear, apply_lora, mark_only_lora_trainable,
merge_lora, parameter_summary. The task is in exercises_en/lora.py,
check: NANOLM_IMPL=exercises_en pytest tests/test_lora.py -v.
Check three things by hand: at the start the model's output does not change (B is initialized
with zeros); after mark_only_lora_trainable the frozen parameters' .grad
stays None; merging does not change the output.
And separately, test_lora_quality_is_bounded_by_rank: rank is a ceiling, not
a "bigger is better" knob. If ΔW is full-rank, a low rank will never cover it.
Code → nanolm/compress.py: magnitude_prune (pruning, that is, zeroing the smallest weights:
global and per layer), prune_ffn_neurons (removing whole SwiGLU neurons, so the matrices get narrower),
low_rank_approximate via SVD (singular value decomposition), distillation_loss with a temperature
and a T² factor. The task is in exercises_en/compress.py, check: NANOLM_IMPL=exercises_en pytest tests/test_compress.py -v.
The distillation from the list above is in code here: with alpha = 0 the loss equals plain cross-entropy, and without the T² factor
the gradient of the soft part would fall as 1/T². The low-rank error matches the Eckart–Young theorem.
Code → nanolm/data.py: a pretraining corpus pipeline built from the functions normalize_unicode, extract_text,
detect_language, quality_filters, mask_pii, exact_dedup, minhash_signature,
lsh_buckets, fuzzy_dedup, decontaminate, run_pipeline, with a per-stage report. The task is in exercises_en/data.py,
check: NANOLM_IMPL=exercises_en pytest tests/test_data.py -v. python scripts/data_pipeline.py gives
a pipeline report and trains the same TINY model on the raw and on the clean corpus.
This is a separate week 15b: data lab: theory (NFKC, MinHash, choosing b and r,
decontamination, PII and licenses), tasks and interview questions. The condensed lab takes another 8 hours. Treat it as a separate practical session,
not a hidden part of the 11-hour core. For the core, take a small dataset, check duplicates across train/validation
and explain the loss mask; complete the full pipeline in week 15b or on an expanded schedule.
Math (Track D): D21: MinHash and LSH for deduplication; D22: bias, variance and shrinkage.
Interview question of the week: "How does LoRA work, and when is it not enough?" A 3-minute structure:
(1) the formula first: W is frozen, a rank-r correction ΔW = B·A is trained; (2) a number: W at 4096×4096 is
16.8 million numbers, the adapter at r = 8 only 65,536, 0.4%; gradients and Adam state are needed only for the adapters,
so of the 16 bytes per parameter (week 9) a frozen weight keeps 2, and with QLoRA half a byte;
(3) initialization: B = 0, so the output does not change at the start; after training B·A is merged into W,
and inference costs nothing extra; (4) the key takeaway: rank is a ceiling, not a "bigger is better" knob:
if the needed change is full-rank, a low rank will never cover it; (5) expect "what if you zero both A and B?":
the gradient of each is proportional to the other, both are zero, and training never starts.
Week outcomes
- I can implement
LoRALinear,apply_lora,merge_loraand pass all the module's tests. - I can compute the number of trainable parameters and the memory savings of LoRA for a given rank and set of layers.
- I can explain exactly what the model will learn if the loss on the prompt is not masked.
- I can describe a near-duplicate deduplication pipeline using MinHash and LSH.
Self-check
- Why is
Binitialized with zeros andArandomly, and what happens if you do it the other way round? - Why is rank a ceiling on LoRA quality rather than a "bigger is better" knob?
- What is decontamination, and why does a benchmark prove nothing without it?